Inception @ COLM 2026
About This Event
About the Event
Join Inception during COLM 2026 for happy hour, featuring refreshments and light bites. Meet our team and connect with others across the research community.
We recently launched Mercury 2.5, our most capable diffusion language model yet. Mercury 2.5 delivers a 40% increase in intelligence over Mercury 2 while maintaining the speed that defines Mercury, generating more than 1,100 tokens per second on widely available NVIDIA GPUs.
Come meet the Inception team, learn more about what we're building, and connect with researchers and engineers working on the future of language models.
This is a closed event and attendance is limited to approved guests. RSVP requests are required, and only guests who receive a confirmation of approval will be admitted.
About Inception
Inception is building the next generation of large language models using diffusion. Unlike traditional autoregressive LLMs that generate tokens sequentially, diffusion LLMs generate and refine tokens in parallel, enabling significantly faster inference.
Our latest model, Mercury 2.5, is our most capable production model yet and, to our knowledge, the largest diffusion language model ever trained. It runs at 1,107 tokens per second, supports a 260K context window, tunable reasoning, parallel tool calls, and structured outputs. Since the launch of Mercury 2, thousands of developers have built with Mercury, dozens of enterprises have put it into production, and usage has grown more than 10x across coding, search, voice, and other latency-sensitive applications.
We’re a team of researchers and engineers working across model training, reinforcement learning, inference, kernels, evaluation, and systems to push diffusion language models forward.
If you’re attending COLM and interested in what comes after next-token prediction, we’d love to see you there.
Our Founding Team
Stefano Ermon (Stanford) — co-inventor of diffusion models, FlashAttention, DPO
Aditya Grover (UCLA) — Decision Transformers, node2vec, d1 reasoning
Volodymyr Kuleshov (Cornell) — MDLM, Block Diffusion
Join Inception
We’re hiring researchers and engineers to help us train larger models, push inference performance, and build the systems behind the next generation of diffusion language models.
Interested in joining the team? Explore our open roles on the Inception careers page.
Hosted by
We email you a private link showing how many people find this event through Mimetic. Tick the box if you are open to sponsors for events like this one and we will get in touch when there is interest. Anything from there is yours to decide.
Location
📍 San Francisco, CA
Want the other 404 SF AI events this week? One email, Monday morning.
Unsubscribe anytime.
Tell us who you are and what you sell. A person at Mimetic reads it and gets back to you by email. Nothing is charged here and we do not sell attendee data.
Get a free growth analysis for your company
See how your website, messaging, and go-to-market strategy stack up, in minutes.
Get My Free AnalysisMore SF events like this
Founder x Investor Run: San Francisco
init() by WorkOS

AWS re:Spark: Founders x Enterprise
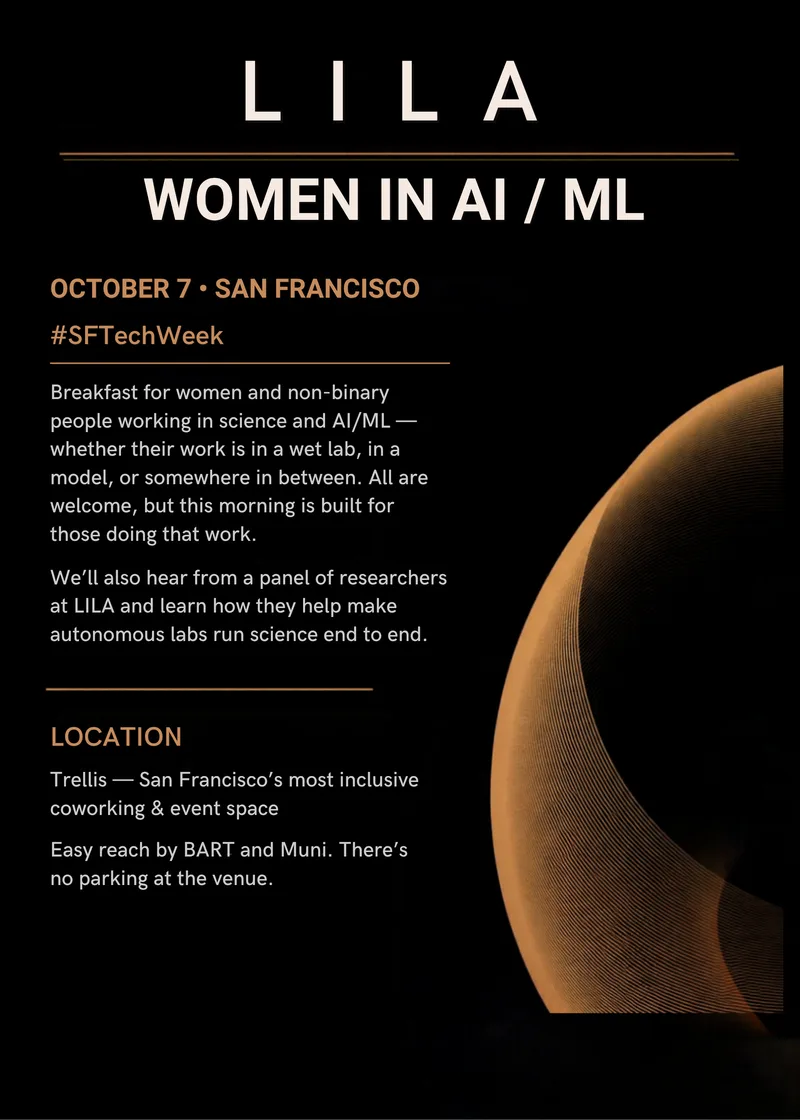
WOMEN IN AI/ML — HOSTED BY LILA